
Introduction — a founder’s quick note
I once watched a driver circle a block three times looking for an open charger and felt that familiar knot of frustration — we’ve all been there. An ev power charging station sat idle at a curb while a nearby lot overflowed with ICE cars; public data now shows urban charger utilization swings wildly by up to 70% day-to-day. So why, I asked myself (and my team), are good chargers so often in the wrong place, or the wrong state — dead, offline, or blocked — when people need them most? I want this piece to be short, honest, and useful: what I’ll describe below mixes what we learned on the street with basic tech terms—edge computing nodes, power converters, and load balancing—and it’s meant to move you from frustration to action. Let’s get into the root causes and then sketch practical fixes.
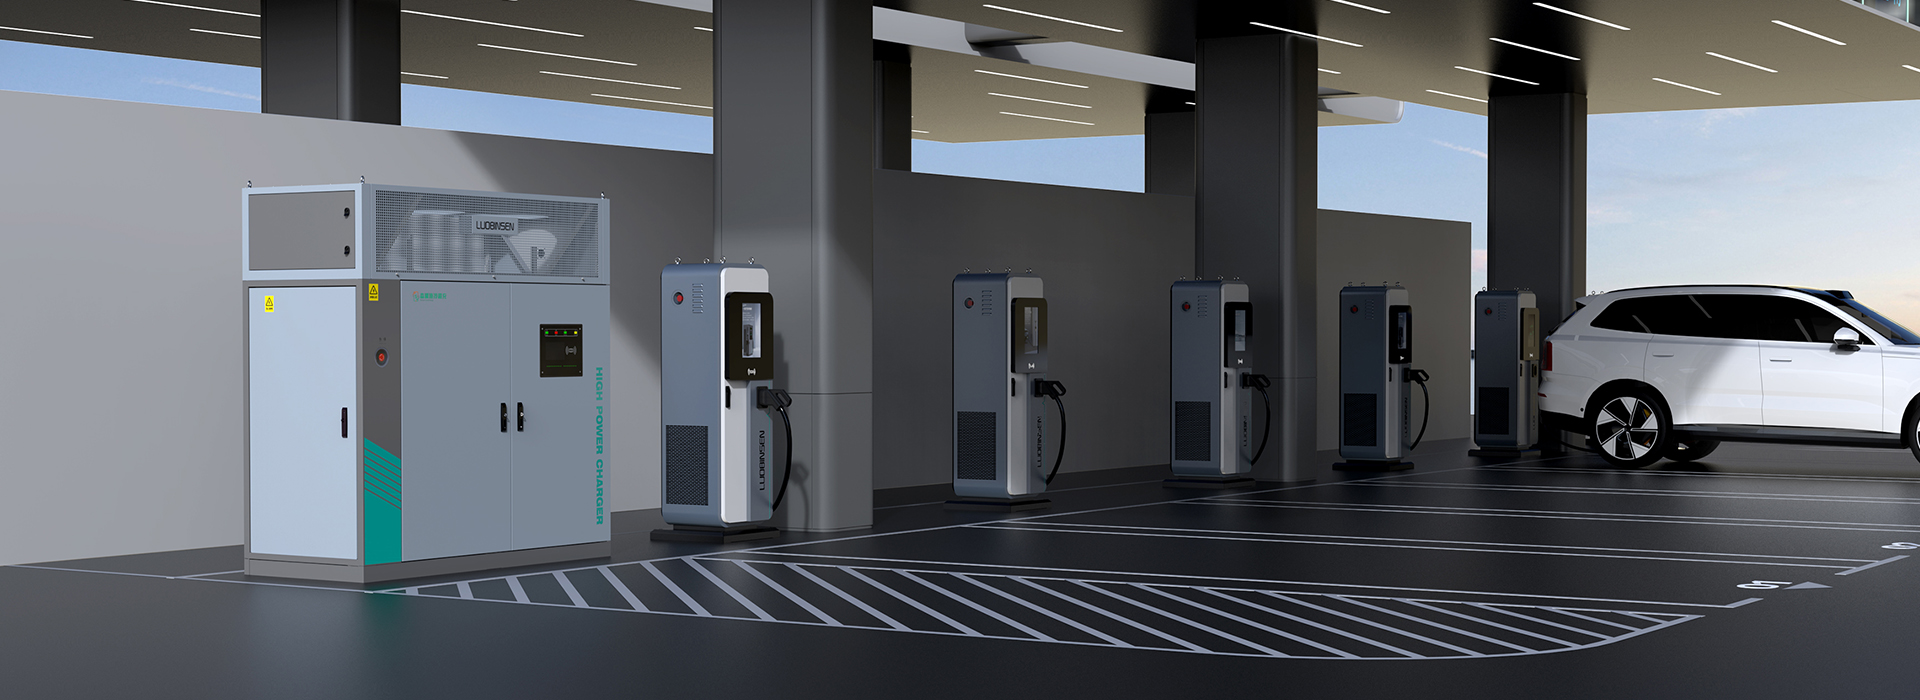
Here’s a quick roadmap: first I’ll show why current approaches fail, then I’ll walk through the tech principles that actually help scale reliable charging. No fluff. Just plain talk and a few clear metrics so you can judge vendors and designs. Onward — to the problems.
Why the usual electric car charging solutions miss the mark
electric car charging solutions get sold as turnkey, but they often hide brittle assumptions. I’ve seen projects where operators bought lots of chargers and assumed drivers would find them — wrong. The fault lines are predictable: poor site selection, weak network telemetry, and systems that can’t handle peak demand. From a systems view, many deployments lack proper power converters tuned for local grid constraints and ignore how bidirectional charging or V2G readiness changes load profiles. That mismatch creates brownouts, long queues, and angry users. Look, it’s simpler than you think: places with real demand need dynamic load balancing, real-time status reporting, and local compute (edge computing nodes) to act fast.
What’s going wrong?
First-person: I’ve audited sites where the software dashboard said “available” while the physical plug was behind a blocked curb — a glaring UX failure. On the technical side, legacy setups lean on central servers and slow polling. When a cluster of DC fast charging stations hits a lunch-hour surge, the central controller lags and chargers throttle arbitrarily. That’s because many systems lack distributed decision logic and sufficient smart metering. The result: chargers trip offline or slow to trickle, which looks like hardware failure but is really a control design problem. We’ve learned that combining local fault detection with networked orchestration cuts downtime dramatically. The pain point for users isn’t a single broken plug — it’s unpredictability. Drivers want confidence and speed; when systems fail to deliver, trust erodes fast.
New technology principles that should guide the next wave
Now let’s look forward. I’ll keep this semi-formal — practical, not preachy. Modern charging architecture should follow three core principles: push decision-making to the edge, design for graceful degradation, and optimize for real human patterns (not just peak kW numbers). Hardware choices matter: modular power converters that can be swapped quickly, charging protocols (like OCPP) implemented cleanly, and support for bidirectional charging let stations serve both drivers and the grid. I recommend vendors that support local orchestration so an outage at one node doesn’t take down the whole site. For example, if a charger’s network link drops, an edge computing node can still run basic scheduling and safety checks. That reduces downtime and keeps customers moving — and honestly, when that happens, you win loyalty.
What’s Next — practical steps and a glance ahead
We’ve started to pilot systems that combine smart metering with priority queues for short-stop charging, and the early results are encouraging — quicker turnover, fewer blocked bays, fewer complaints. There’s also a clear role for an open, transparent operations dashboard that tells staff what to fix first. If you’re evaluating an electric vehicle charger supplier, look for those capabilities: modular hardware, local control, clear telemetry, and a proven service model. Also, accept that deployments are social as much as technical — signage, curb design, and user education matter. Small actions can yield big user experience wins — funny how that works, right? — and they compound over time.
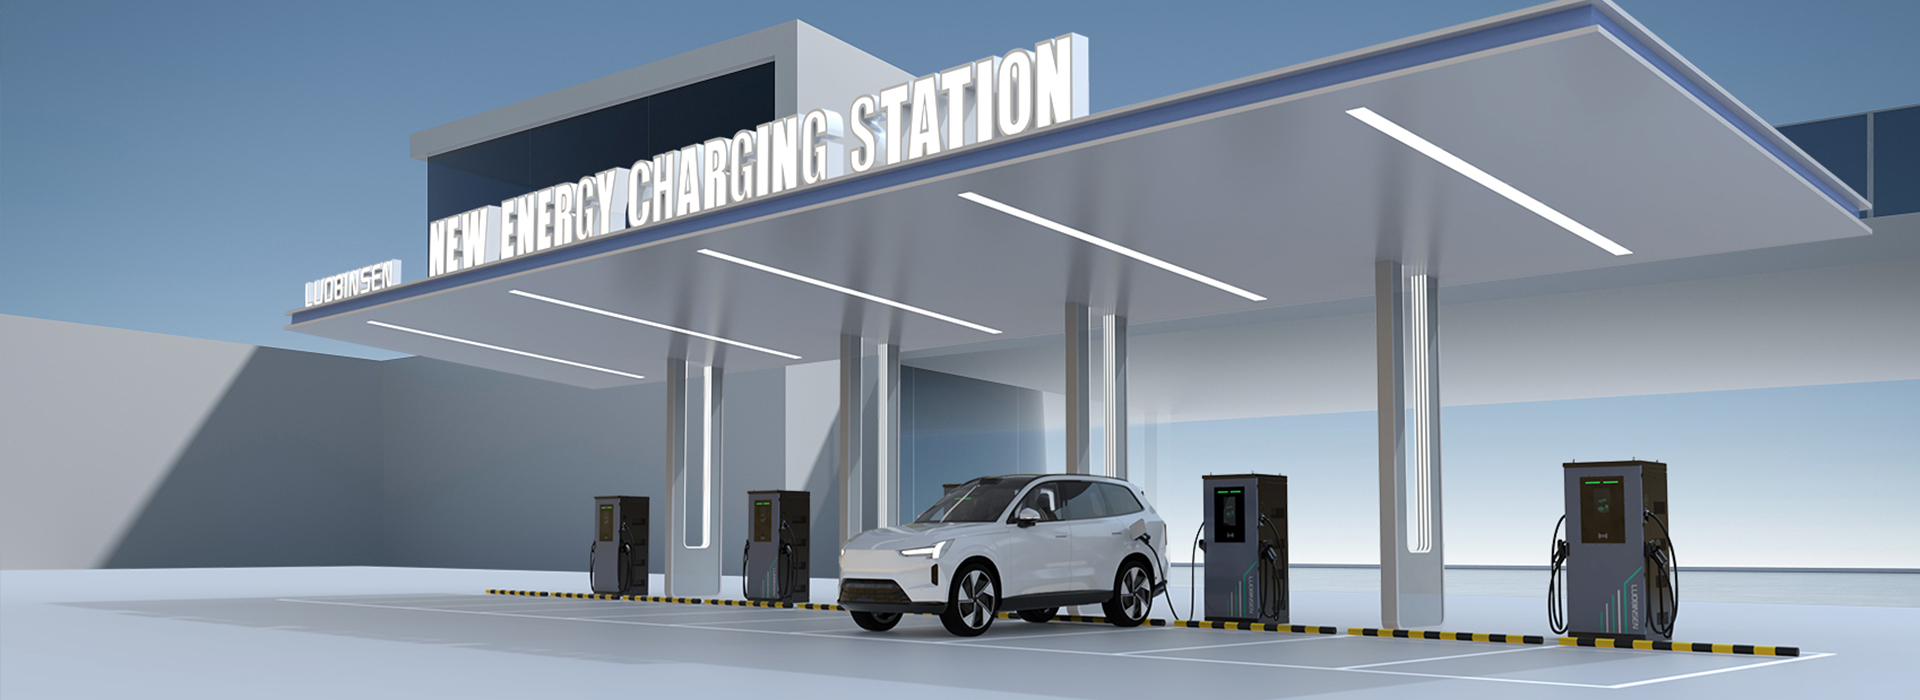
Three quick evaluation metrics I use when choosing solutions: uptime percentage under real load (not vendor lab claims), mean time to repair (MTTR) for a physical charger, and measured queue length during peak hours. Those numbers tell a clearer story than spec sheets. If you want a partner that understands both product and people, check out Luobisnen. I’m happy to walk through criteria and examples — we’ve learned the hard lessons so you don’t have to.